About Us
We help executives make confident AI vendor decisions in days, not months.
If you’ve been handed the “figure out AI” mandate with a deadline, a budget, and vendors already circling—we’re who you call.
Who We Are
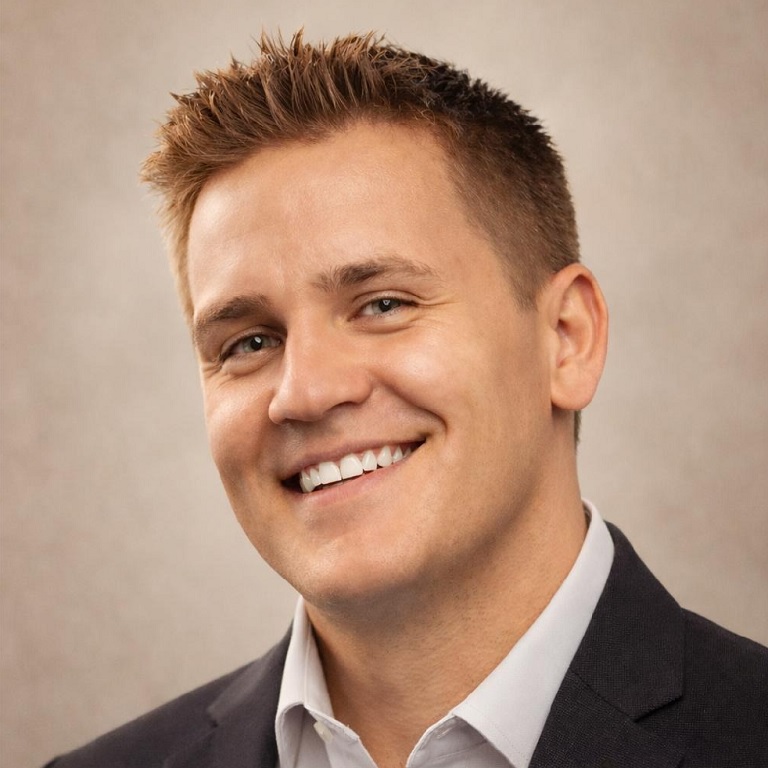
Chris Sprague
Background: B.S. in Aerospace Engineering and Applied Mathematics, University of Colorado BoulderChris led navigation and timing systems testing at Lockheed Martin and held technical leadership roles at Sierra Nevada Corporation. He's rebuilt underperforming systems and teams throughout his career, focusing on diagnosing where work gets stuck and aligning incentives with outcomes.
Forged in High-Stakes Industries
Our team has held roles at:

We’ve worked inside organizations where technology decisions carried real weight—and where we saw firsthand what happens when vendor purchases get made without practitioner input.
AI Systems We’ve Built
We understand how to evaluate AI tools because we’ve built them:
- Healthcare — AI scribe that turns doctor-patient conversations into structured clinical notes, allowing doctors to focus on patients instead of paperwork
- Customer Operations — AI support agent with knowledge base Q&A and intelligent team routing, reducing response times from hours to seconds
- Software Quality — Human-guided AI test generation, from manual scripts to automated test suites covering millions of lines of code
- Developer Productivity — Orchestration platform for directing swarms of AI agents to build high-quality software at scale
- Defense Compliance — AI verification of battlefield software against military standards, where errors have life-or-death consequences
We build tools for ourselves too — we know the difference between a demo and a deployable product because we’ve had to make that distinction.
Every build required evaluating models, designing prompts, and architecting infrastructure — with real consequences for getting it wrong. That’s what shapes how we evaluate vendors for you.
Why That Matters for You
We’ve evaluated AI from three angles:
As builders inside enterprises. We contributed to shipping AI products. We know what it takes to move from pilot to production and where vendor claims break down.
As practitioners using AI tools. We’ve piloted products, pushed them to their limits, and provided input on what actually works versus what demos well.
As founders building our own AI systems. We’ve evaluated and selected models, frameworks, and tools with our own resources on the line.
Evaluations can fail because the evaluators have never built or used these tools in production. They’re comparing slide decks.
We compare reality to reality.